Quantification¶
andes is a search engine and a quantification engine. Identification and quantification share one run, one index and one error model, so a quantity always knows which identification supports it.
flowchart TD
    S["Search"] --> PIN["PSMs"]
    PIN --> PC["Percolator q-values"]
    PC --> L{"Label type"}
    L -->|"TMT / iTRAQ"| T["--tmt<br/>reporter ions per PSM<br/>impurity correction<br/>quantification gate<br/>optional --tmt-unmix"]
    L -->|"label-free"| F["--lfq<br/>MS1 features per precursor<br/>isotope-envelope matching"]
    F --> M["--mbr<br/>library + RT alignment across runs<br/>transfers with their own q-values"]
    T --> O["QPX feature view<br/>(Parquet)"]
    M --> O
O --> P["Protein inference and<br/>protein quantification"]| Mode | Flag | What you get |
|---|---|---|
| Reporter ions | --tmt |
per-PSM reporter intensities (TMT/iTRAQ), isotope-impurity corrected, with a precision gate and a purity-weighted roll-up weight |
| Interference removal | --tmt-unmix |
per-scan co-isolation estimate and unmixed channels; details |
| Label-free | --lfq |
MS1 feature quantities per precursor and run |
| Match between runs | --mbr |
quantities in runs without an identification, each with an evidence type and its own q-value; details |
| Cluster scale | andes quant library / extract / finalize |
the same MBR split into per-run steps for many runs on a cluster |
Label-free accuracy on ProteoBench¶
Median |ε| is the median absolute error of the measured log-ratio against the known mixture
ratio (lower is better). Counts are precursors quantified in at least 3 runs where the
leaderboard gives them. andes rows are defaults at transfer q 0.01 (2026-10-23, 2051616b);
the other rows are the public leaderboard snapshot of 2026-07-16.
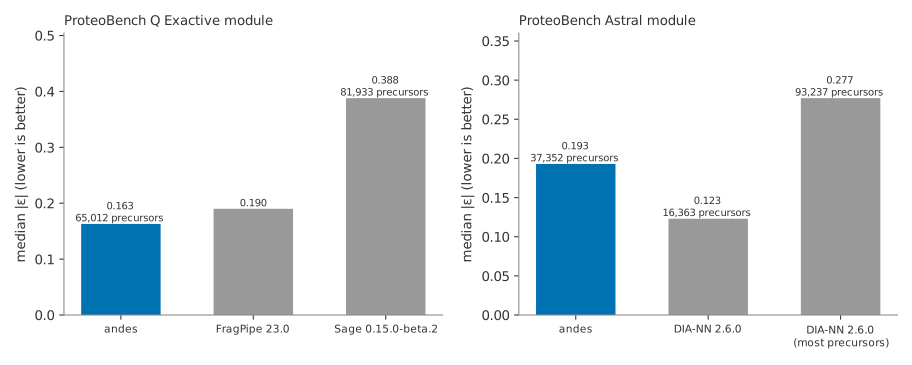
Read the figure with its conditions:
- Q Exactive module (PXD028735, 6 runs, human/yeast/E. coli): andes reports 65,012 precursors in at least 3 runs with CV 0.118. The leaderboard row with the most precursors (Sage 0.15.0-beta.2, 81,933) has a higher median error, and its transferred values are not error-controlled.
- Astral module (PXD070049, 6 runs): DIA-NN 2.6.0 has a lower median error than andes (0.123 against 0.193) at 16,363 precursors; its most-precursors setting has 93,237 at 0.277.
- Error control: PSM FDP 0.83–0.85% and entrapment-only quantified precursors 0.20–0.22% on the Q Exactive set. Not measured on the Astral set.
Cost: 6.9k CPU-seconds for the 6 Q Exactive runs, 6.4k for the 6 Astral runs.
TMT¶
- Reporter extraction and impurity correction match OpenMS IsobaricAnalyzer exactly on the same scans.
- Known ratios (PXD007683, human + yeast TMT11, 11 SPS-MS3 fractions): yeast A/C log2 ratio 1.591 against the expected 1.585, protein-level MAE 0.212; 9.6 minutes and 17.5 GB on 16 threads.
- Interference on a knockout design is on the unmixing page.
At scale¶
A 500-run study (PXD042233: Q Exactive HF/HF-X and Exploris 480) gives 243,895 precursors in at least 3 runs and 9,208 protein groups at transfer, precursor and protein q ≤ 0.01, for 146 CPU-hours end to end. See the benchmark report for the conditions, and §10 of the reference for every parameter.