Home
The data-driven peptide search engine and quantification engine of the quantms ecosystem. Spectra and a FASTA go in; Percolator-ready PSMs and, on request, protein groups and label-free or TMT quantities come out. The scoring model is chosen per file from its metadata.
What it does
-
Reads your files as they are
mzML, MGF, native Thermo
.rawand Bruker timsTOF.d. One of 17 bundled scoring models is picked from the file's activation, resolution and isobaric label. How it works -
Leaves the FDR to Percolator
andes computes no production FDR. It writes the PIN, and Percolator, run by you or by
--rescore, decides what passesq ≤ 0.01. Quick start -
Optional modes
Co-isolated peptides (
--chimeric), secondary modifications (--refine), and intact N-glycopeptides (--glyco). Modes -
Quantification built in
TMT/iTRAQ reporter ions (
--tmt) and label-free MS1 features with match between runs (--lfq), from the same run as the search. Quantification
The pipeline at a glance
flowchart LR
    S["Spectra<br/>mzML · .raw · .d"] --> M["Pick model<br/>per file"]
    F["FASTA"] --> I["Out-of-core<br/>fragment index"]
    M --> R["Retrieve and score<br/>top candidates"]
    I --> R
    R --> C["Optional passes<br/>chimeric · refine · glyco"]
    C --> P["PIN"] --> PC["Percolator<br/>owns the FDR"]
    PC --> O["PSMs · proteins · sites<br/>quantities (QPX)"]
Features built around trust in a result
-
Knockoff variant FDR
Variant claims get a null that makes the same mistakes as the claim: 65% to 2.5% true FDP on a genotyped dataset. Read more
-
Chimeric cascade
A second peptide from the residual spectrum: 43k to 66k Astral PSMs at an equal true FDP of 1%. Read more
-
Error-controlled match between runs
Every transferred quantity says what supports it and carries its own q-value. Read more
-
TMT interference unmixing
Per-scan co-isolation estimated from MS1, with no reference channel. Read more
All distinctive features The quantms ecosystem
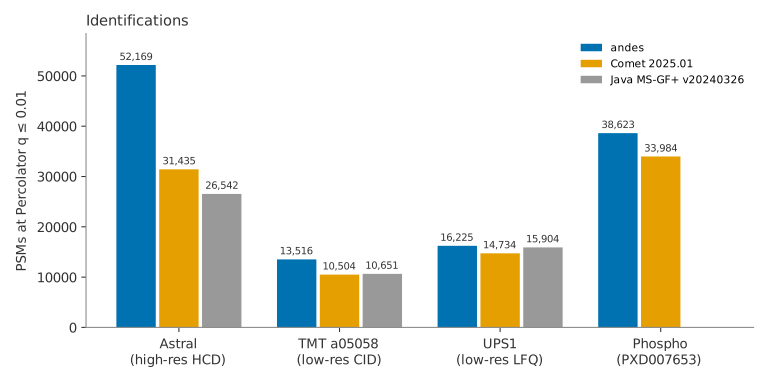
Identifications, measured the same way
PSMs at Percolator q ≤ 0.01 on public reference datasets, rescored identically for every
engine on the same 8-core machine. The conditions, dates and commits behind each bar are on the
benchmarks page.
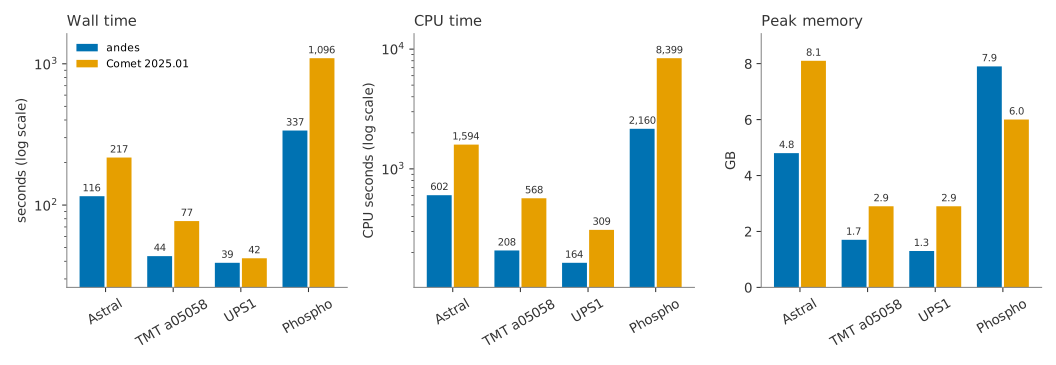
CPU time and memory
Same machine, same rescoring, 8 threads. Wall time, CPU time and peak memory for andes and Comet on four datasets; phospho is the one set where andes uses more memory.
Details and conditions: benchmarks.
Search and quantification
andes quantifies as it searches. Label-free runs get MS1 features and match between runs where every transferred value carries its evidence type and its own q-value; TMT runs get impurity-corrected reporter ions with a precision gate.
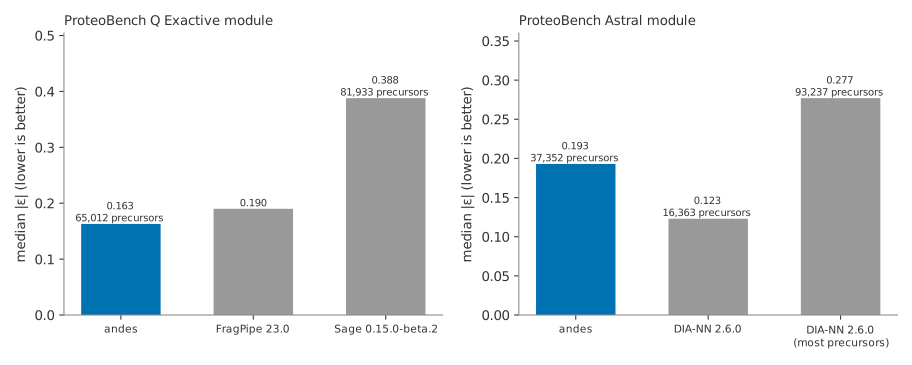
On the Astral module another tool has the lower median error; the quantification page shows both modules with their conditions.
Glycoproteomics
Intact N-glycopeptide search (--glyco) is benchmarked against five published tools on PXD065680,
with entrapment error estimates for andes.
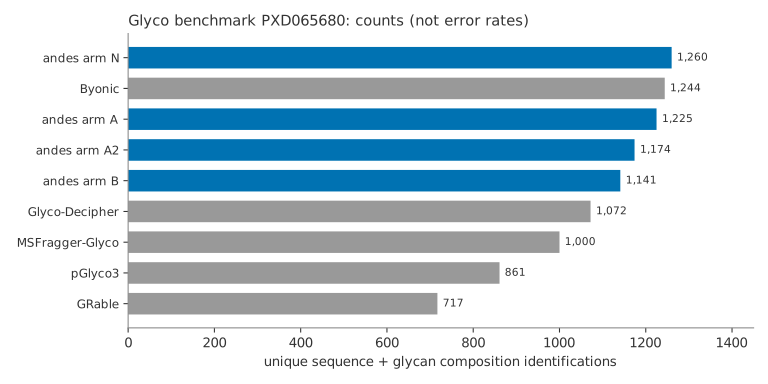
These are counts, not error rates; andes's entrapment FDP is 1.04–1.50% at a nominal 1%. See the glyco benchmark for the overlap, evidence tiers and every deviation from the paper's protocol.
Install
cargo install --git https://github.com/bigbio/andes --bin andes
Release archives for Linux, macOS and Windows are on the releases page. Details: Install.